Task success with uncertainty
Deterministic assertions, rubric judges, paired effects, and intervals—without hiding inconclusive results.
Compare model, prompt, tools, retriever, safety policy, and agent configuration as one deployment candidate. Prooflane measures the tradeoffs and tells you when the evidence is too weak to pick a winner.
$ prooflane benchmark run benchmark.yaml

suite      support-agent-v7
candidates sonnet / gpt / local-70b
cases      180 × 5 paired trials

quality    gpt +3.8 [1.2, 6.1]
cost       local-70b −61%
latency    sonnet p95 1.84s
security   gpt failed tool-safety gate

verdict    sonnet — Pareto eligible
health     91 / 100 · 2 power warnings
A candidate wins only when it remains useful, affordable, fast, reliable, and inside your safety gates.
Deterministic assertions, rubric judges, paired effects, and intervals—without hiding inconclusive results.
Input, output, cache and reasoning usage stay explicit. Unknown pricing remains unknown, never zero.
TTFT, p50 through p99, retries, rate limits, consistency, flakiness, and categorized failures.
Correct tool choice, argument validity, unnecessary calls, task completion, and unsafe actions.
Retrieval quality, grounding, citations, poisoning resilience, and end-to-end answer outcomes.
A critical breach cannot be averaged away by a high quality score or a low price.
Configure real model and application candidates locally, then inspect methodology health and decision-grade evidence.
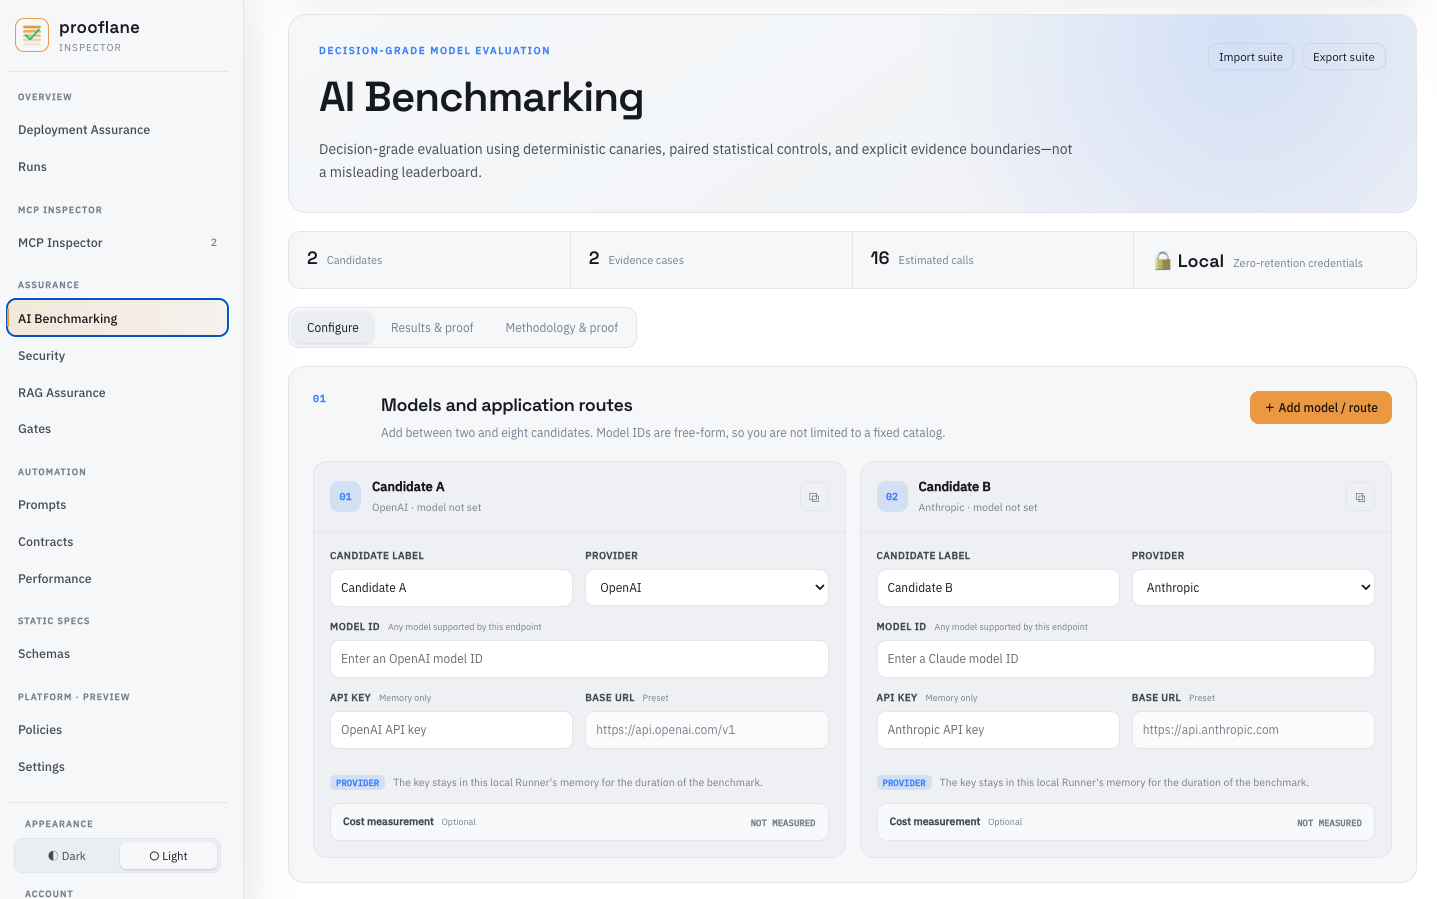
Configure candidates, run paired trials, inspect the Pareto frontier, and export a standalone report.
prooflane benchmark validate benchmark.yamlprooflane benchmark run benchmark.yaml --seed 20260809prooflane benchmark report run.json --html report.htmlProoflane evaluates the methodology as well as the candidates, exposing blind spots before a dashboard creates false certainty.
Coverage by capability and risk, judge calibration, positional and verbosity bias, duplicates, contamination, flaky assertions, statistical power, and a reproducibility manifest.
Version candidates, datasets, assertions, judges, budgets, and gates.
Run paired, interleaved trials through provider, MCP, agent, or RAG adapters.
Calculate effects, intervals, consistency, power, and Pareto eligibility.
Export JSON, HTML, CSV, JUnit, or SARIF and enforce CI policy.
prooflane benchmark run benchmark.yaml --json run.json
prooflane benchmark compare baseline.json run.json
prooflane benchmark report run.json --html report.html
Benchmark the system your users will actually experience.
30-day full-access trial. No credit card required.
Prooflane is beta software. Benchmark scores and generated recommendations are informational, may be incomplete, and are not guarantees of performance, security, compliance, or future provider behavior. Illustrated terminal output and benchmark-health graphics on this page explain the intended product experience; they are not results from a production customer run.